TasksAvailable
Build the conditions.
Seeded tasks at a difficulty you choose, on your own tools, with checks the system under test can't see.
Poisson LabsChange control for stochastic systems · open source + cloud
Whether you’re shipping an AI agent, a robot controller, or a learned policy, a single headline number hides where the system fails—and moves a few points with nothing changed.
Keep the stack, simulator, and runner you already have. Poisson compares your system before and after a change, condition by condition, on matched seeds and cases, and tells you what improved, what regressed, and what is still too close to call before the change ships.
significantly safersignificantly worseno significant changethe average
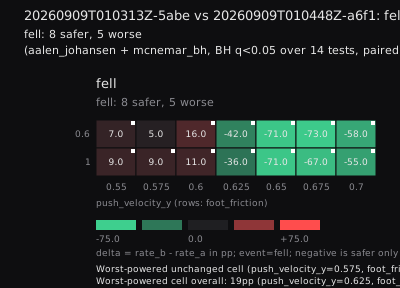
microduck-walking@v1
8 better · 5 worse · 1 too close to call, below a 8-point limit
McNemar’s test per condition on 100 paired trials, Benjamini–Hochberg at q < 0.05. The unchanged condition could have shown a rise of 8 points or more.
These files are as Prove 0.0.1 wrote them, in that version’s green and red.
Published on AI agentswalking robotsa vision encodera multi‑agent benchmarktraining stability
01How it works
Keep what you run. Poisson says what a change did to it, condition by condition.
Agents
OpenAI Agents SDK, LangGraph, CrewAI
Evals and tracers
DeepEval, Ragas, promptfoo, Inspect, OpenAI Evals, Braintrust, Weave, LangSmith
Simulators
MuJoCo, Isaac Lab, PyBullet, Brax
Compute
AWS, GCP, Azure, Your machine, Modal
TasksAvailable
Seeded tasks at a difficulty you choose, on your own tools, with checks the system under test can't see.
BreakIn development
It will search the conditions for the ones that break the system, and keep each as something a fix can be checked against.
TracePrivate wheel
It reads the runs you already have and says which step they die at, with the unchanged version as the control.
review, the stage the seal named. Read the studyProveAvailable
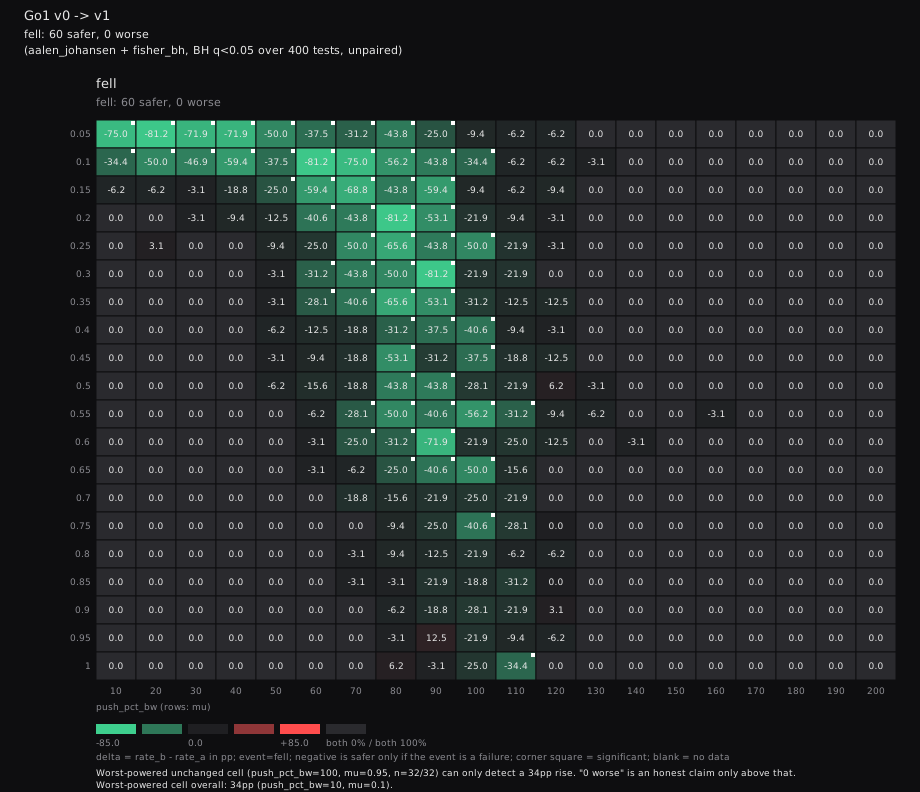
Every condition, before and after, on the same seeds: 60 safer, 0 worse, 340 with no significant change. In CI, a regression fails the check.
02The problem
We ran the same airline agent twice on τ²-bench: identical configuration, identical seed, temperature zero. The score barely moved. Underneath, 44 of 200 tasks flipped: 23 passed only in the first run and 21 only in the second, and they cancelled out.
pairs still identical after each model calln = 200
one task, both runs, call by callidentical, then not
Both runs, identical
get_reservation_details Call 4: the runs part. The agent is given the same 3,659 tokens in both runs. It writes 96 tokens in one and 129 in the other.
Run R 20260915T210140Z-4847
transfer_to_human_agents Passed solved · COMMUNICATE 1 · DB 1
Run R′ 20260915T211148Z-965d
cancel_reservation transfer_to_human_agents Failed unsolved · COMMUNICATE 1 · DB 0
Top-line scores stay flat while dozens of tasks flip underneath. Measure the noise before you call anything a change.
03Proof
The same method on a different kind of system: the thing under test changes, the way its failures are found and measured does not. We mapped a Go1 walking policy across 400 conditions of floor friction and lateral push. The map showed two conditions its training had never covered; we retrained on those, then ran both policies through every condition again, 32 times each on the same seeds.
340 showed no significant change. For the least-powered of them, the run could not have detected a rise in the fall rate under 34 percentage points. That limit is reported with the result.
60 conditions significantly safer after the retrain0 significantly worse, anywhere in the 400
04The tools
Find where runs fail. Measure whether a change helped. Map how difficulty changes outcomes. Search for the conditions that break your system. Train an agent on its own failures. Use them on your own machines, or in CI with Poisson Cloud. They grade by code and statistics, never by another model, and send nothing home.
poisson-trace fix-check OLD NEW --store ROOT --event NAME \ ( --failing-from RUN | --inputs all ) --max-mde X
pip install poisson-tracepip install poisson-prove# where do runs die, over the step indexpoisson-trace where RUN --store ROOT --event NAME# do two runs' survival curves differpoisson-trace compare A B --store ROOT --event NAME --max-mde-hr X# did the change make runs fail less, with the old version as the controlpoisson-trace fix-check OLD NEW --store ROOT --event NAME \ ( --failing-from RUN | --inputs all ) --max-mde X# which inputs moved, corrected across all of thempoisson-trace changes A B --store ROOT --event NAME
poisson-prove check --event violated --fail-on worse pip install poisson-provepoisson-prove init --example# 1. sweep the conditions, before the changepoisson-prove sweep --yes# 2. sweep again after it, on the same seedspoisson-prove sweep --yes \ --target poisson_prove.examples.mock_agent:rollout_patched \ --pair-with latest# 3. compare the pair into report.md, heatmap.svg, receipt.htmlpoisson-prove report --event violated --x tool_fail_rate --y task_id# in CI: exit 4 if any condition came back significantly worsepoisson-prove check --event violated --fail-on worse
These files are as Prove 0.0.1 wrote them, in that version’s green and red.
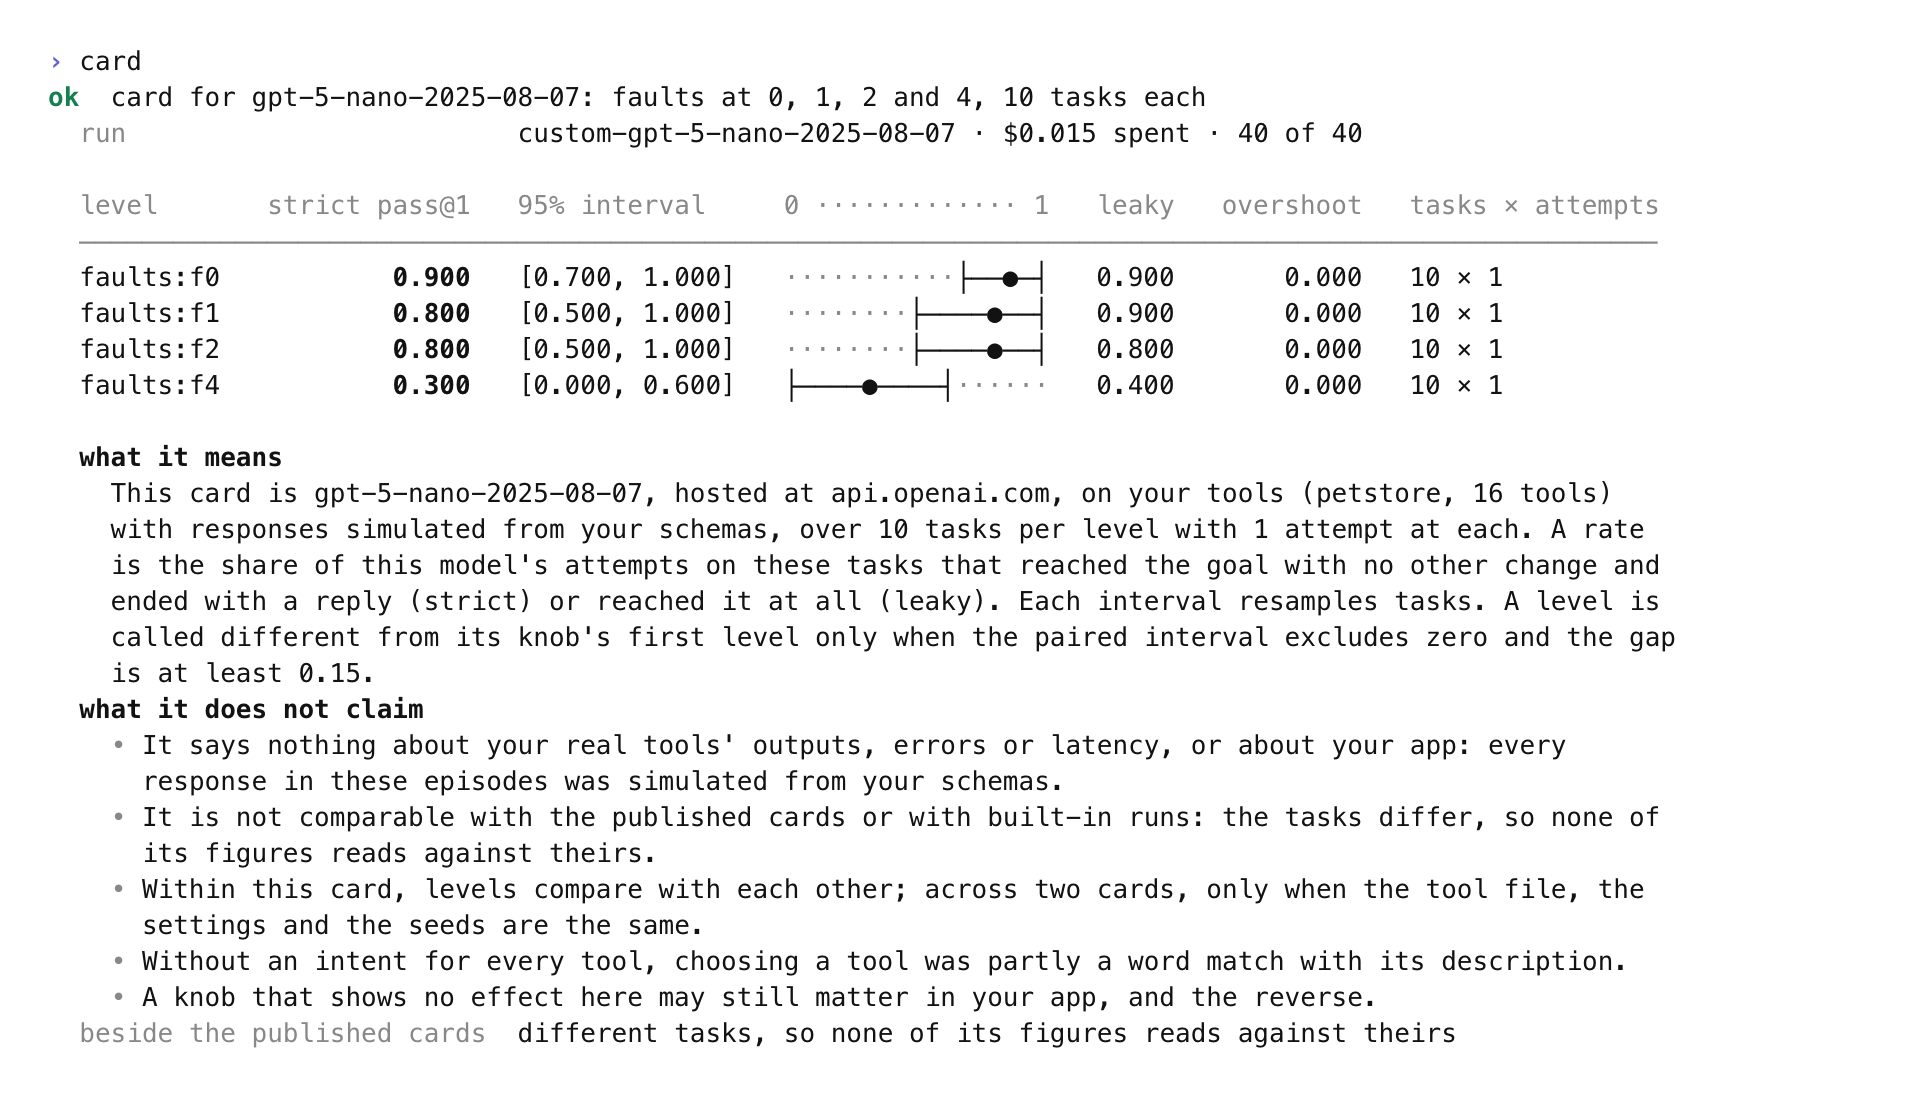
| Depth | Pass@1 | Strict, 95% interval · ○ leaky | vs. previous level |
|---|---|---|---|
| d1 | 54.7% | baseline | |
| d2 | 39.7% | −15pp · distinct | |
| d3 | 23.7% | −16pp · distinct | |
| d5 | 17.7% | too small to call | |
| d8 | 87.0% | +69pp · distinct |
Break runs your agent many times while it changes what the agent meets in production, keeps only the changes that fail more often than an untouched control, and hands each one over as a replayable condition a fix can be checked against.
The gym trains an agent against checks it cannot see, draws its practice from where it currently fails, and reports for each checkpoint whether training helped, at a stated confidence.
05In your CI
Establish a baseline, rerun the same conditions on every pull request, and block the merge when a condition is significantly worse.
Run your agent across the conditions you care about, each run on a seed.
The same conditions on the same seeds, so each one is compared with itself.
Improved, regressed, or too small to call, condition by condition. A regression fails the check.
It fails on real regressions, not on noise. A condition fails the check only when it is significantly worse than its own baseline, with the correction for testing every condition at once built in. You get a pass or a fail on the pull request; the full receipt (the test per condition, Benjamini–Hochberg at q < 0.05, and each condition’s detection limit) is one click away. A regression smaller than that limit can pass, and the report says so.
on: pull_requestjobs: agent: steps: - name: Check the agent run: | poisson-prove sweep agent.toml \ --target my_agent:rollout \ --pair-with <main-run> --yes poisson-prove check <main-run> <this-run> \ --event violated --fail-on worse
06What it leaves you
A failure doesn’t end as a line in a report. It becomes a test on every pull request, training data aimed at exactly that failure, and the starting point of the next search. The first is in private preview; the other two are being built.
1Into your CIAvailable
Each condition that broke the agent is saved as a file: the change, the seed and the failure rate under it. It re-runs on every pull request as a standing check, so a fixed failure stays fixed.
2Into trainingIn development
The same condition on the same seed, failing before a change and passing after, is a preference pair. So are passing and failing runs within one condition, each with the prompt, retry or tool-schema patch behind it. For a robot policy, training ranges shift toward where it broke, as in the Go1 retrain.
3Into MonteIn research
Labelled failures, each with its trace and the exact condition, are what Monte is built to learn from: a model of where agents fail that starts the next hunt where failure is most likely. It will learn only from records whose owner turned training on.
Nothing counts as fixed until it is re-run. A retrained agent goes back through the same conditions on fresh seeds, and the result is a receipt like any other. The Go1 retrain is this loop, run once: the map showed two conditions training had missed, and the policy was retrained on exactly those.
07How we count
Establish how much the system varies when nothing was changed on purpose.
Match conditions and seeds across the baseline and the new version.
Report changes by condition, not just as an average. An average can improve while 5 conditions get worse.
State the smallest effect the study was equipped to find.
MATH ASINFRASTRUCTURE.