Tools · open source · 0.4.2
Tasks
A pass rate tells you little when you can’t move the difficulty on purpose, and when another model decides what counted as a pass.
Tasks generates tool-use tasks at a difficulty you set, from a seed. Each task has one right end state, checked by code that comes out of the same generator, so nothing is graded by another model and the same seed gives the same task on any machine.
GitHub · PyPI · Docs · Changelog · Run this on your agent
The video’s text
- 0:00$ pip install poisson-tasks · poisson labs · tasks 0.1.0 · Evals measure what you test. · Tasks varies the conditions. · Your schemas. No live backend calls.
- 0:06The eval passed. · The tool call failed. · The task didn't.
- 0:10Poisson Tasks · Controlled failure tests. · Introduce a failure. Measure what the agent does next.
- 0:13tools: OpenAI, MCP, OpenAPI · responses: simulated from schemas · backend: never called · difficulty: one variable at a time · grading: deterministic code
- 0:18Pass@1 by injected fault count · gpt-5-nano · petstore · faults:f0 0.900 [0.700, 1.000] · faults:f1 0.800 [0.500, 1.000] · faults:f2 0.800 [0.500, 1.000] · faults:f4 0.300 [0.000, 0.600] · 10 tasks per level · 1 attempt · 95% intervals · task-level bootstrap
- 0:25Vary one condition at a time. · Tool failures · History length · Competing goals · Chain depth
- 0:28Find the failure. Before the release.
- 0:31poisson labs · tasks 0.1.0 · pip install poisson-tasks · poissonlabs.ai/tasks
Start
Needs Python 3.11 to 3.13, on macOS or Linux. Check with python3 --version
first: on an older Python, pip won’t install this release, and may install an empty
placeholder in its place without a word.
python3 --version
pip install poisson-tasks
poisson-tasks
The last line, with nothing after it, opens a guided session in your terminal. In a new folder it walks you through setup, one task to look at, the run and your first card. Nothing calls a model until you say yes to the run’s cost.
Who it is for
Agent teams
Tasks built on your own tools: an OpenAI tools file, an MCP server or tool list, or an OpenAPI document. Every call is answered by a simulator shaped by your schemas, so your backend is never called, and the card shows where your setup starts to break.
Here is one real run, on the Petstore API with gpt-5-nano and 10 tasks at each level. With no failed calls the pass rate was 0.90. With four, it was 0.30.
People training models
Checkable tool-use tasks at the difficulty you choose, scored exactly, and a card for each model you run. The same tasks export to verifiers, to run under your own loop.
poisson-tasks export --to verifiersThe guided session
Type poisson-tasks and it walks you through a first run.
With nothing after it, the command opens a guided session in your terminal. In a new folder it takes a first run in five steps: set up, one task to look at, the run, the card, and what next. In a folder that is already set up it shows where you are and offers the next steps. Nothing calls a model until you say yes to the run’s cost.
Every action in the session is one of the command’s own verbs, and each ends with the command line that does the same thing, so what you did in the session can run from a script. There is no AI in the session itself.
Opening
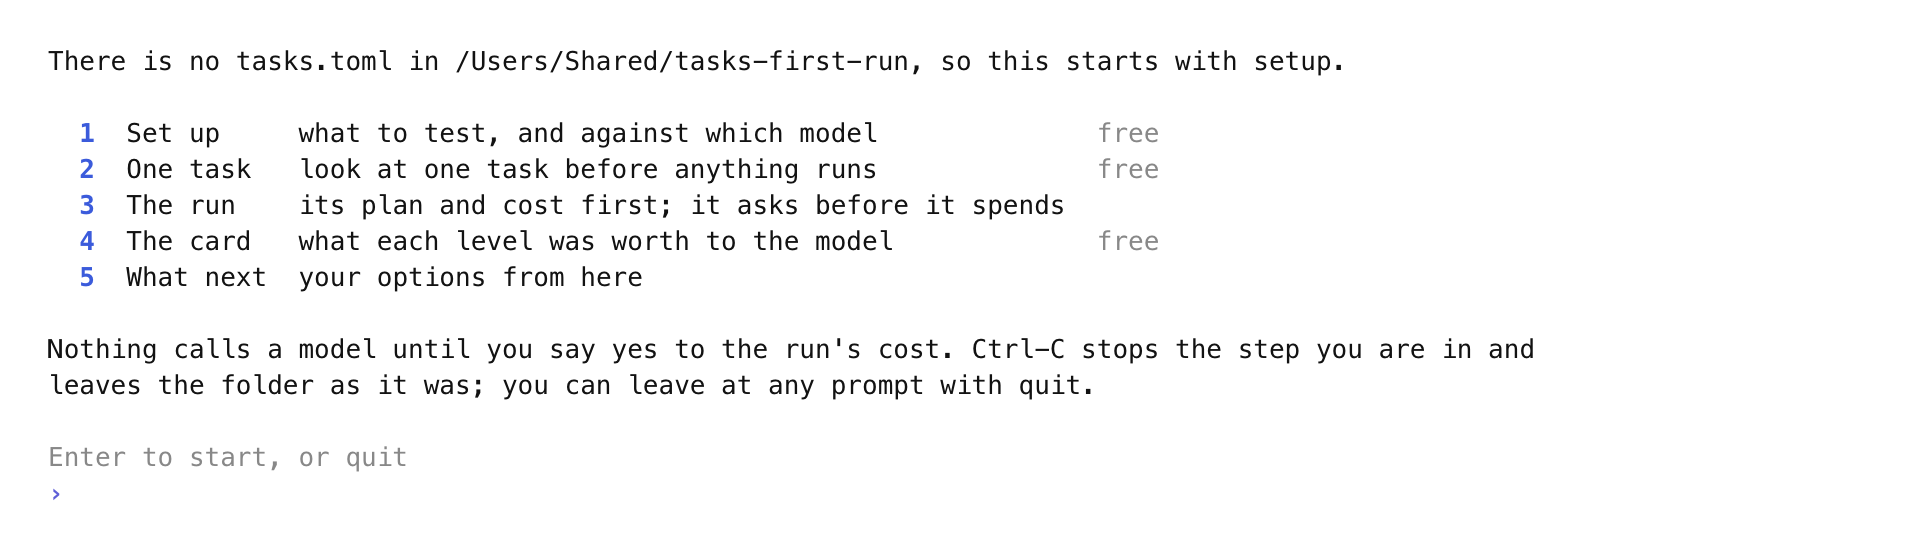
In a new folder the session opens with its five steps and says what it will not do: nothing calls a model until you say yes to the run’s cost.
As text
There is no tasks.toml in /Users/Shared/tasks-first-run, so this starts with setup.

  1  Set up     what to test, and against which model              free
  2  One task   look at one task before anything runs              free
  3  The run    its plan and cost first; it asks before it spends
  4  The card   what each level was worth to the model             free
  5  What next  your options from here

Nothing calls a model until you say yes to the run's cost. Ctrl-C stops the step you are in and
leaves the folder as it was; you can leave at any prompt with quit.

Enter to start, or quit
›
Setup
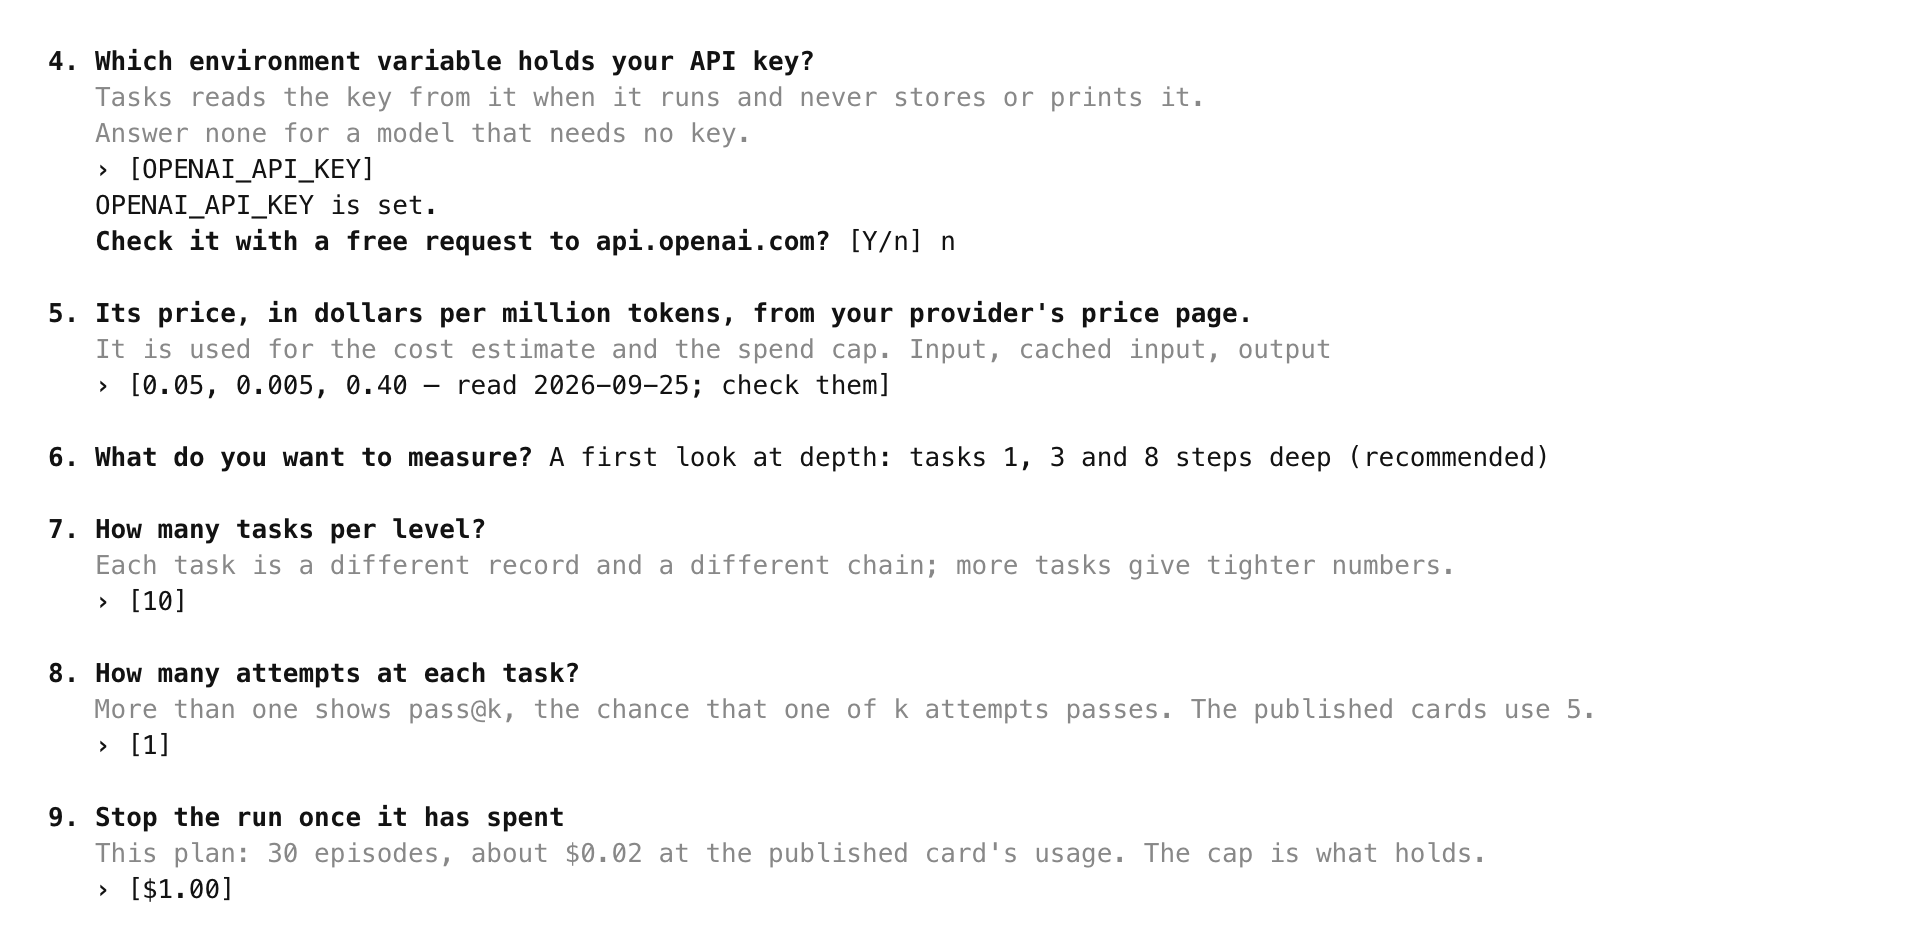
It asks which model to test, which environment variable holds the key (the key itself is never stored or printed), the price, what to measure, how many tasks and attempts, and where to cap spending. The last question prints the plan’s cost before anything runs: 30 episodes, about $0.02.
As text
4. Which environment variable holds your API key?
   Tasks reads the key from it when it runs and never stores or prints it.
   Answer none for a model that needs no key.
   › [OPENAI_API_KEY]
   OPENAI_API_KEY is set.
   Check it with a free request to api.openai.com? [Y/n] n

5. Its price, in dollars per million tokens, from your provider's price page.
   It is used for the cost estimate and the spend cap. Input, cached input, output
   › [0.05, 0.005, 0.40 — read 2026-09-25; check them]

6. What do you want to measure? A first look at depth: tasks 1, 3 and 8 steps deep (recommended)

7. How many tasks per level?
   Each task is a different record and a different chain; more tasks give tighter numbers.
   › [10]

8. How many attempts at each task?
   More than one shows pass@k, the chance that one of k attempts passes. The published cards use 5.
   › [1]

9. Stop the run once it has spent
   This plan: 30 episodes, about $0.02 at the published card's usage. The cap is what holds.
   › [$1.00]
One task
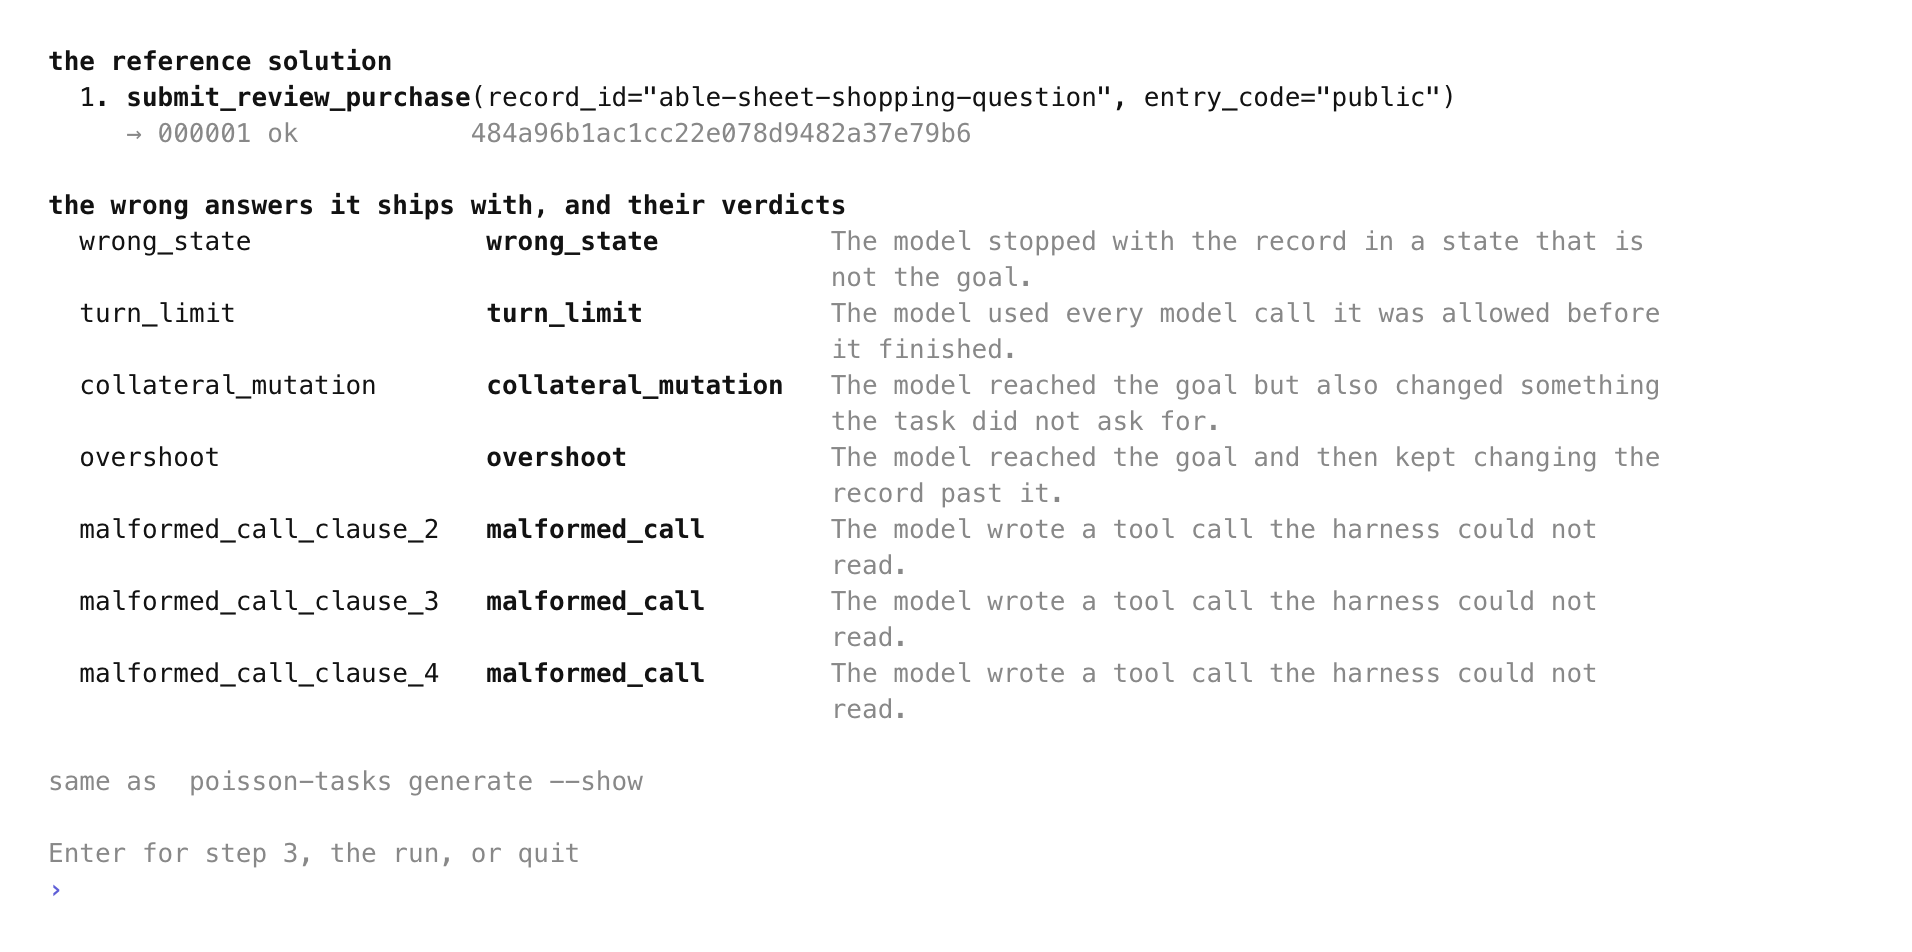
The task’s reference solution, and each wrong answer it ships with, with the verdict its own checker gives it. No model is called, and no model judges.
As text
the reference solution
  1. submit_review_purchase(record_id="able-sheet-shopping-question", entry_code="public")
     → 000001 ok           484a96b1ac1cc22e078d9482a37e79b6

the wrong answers it ships with, and their verdicts
  wrong_state               wrong_state           The model stopped with the record in a state that is
                                                  not the goal.
  turn_limit                turn_limit            The model used every model call it was allowed before
                                                  it finished.
  collateral_mutation       collateral_mutation   The model reached the goal but also changed something
                                                  the task did not ask for.
  overshoot                 overshoot             The model reached the goal and then kept changing the
                                                  record past it.
  malformed_call_clause_2   malformed_call        The model wrote a tool call the harness could not
                                                  read.
  malformed_call_clause_3   malformed_call        The model wrote a tool call the harness could not
                                                  read.
  malformed_call_clause_4   malformed_call        The model wrote a tool call the harness could not
                                                  read.

same as  poisson-tasks generate --show

Enter for step 3, the run, or quit
›
The run
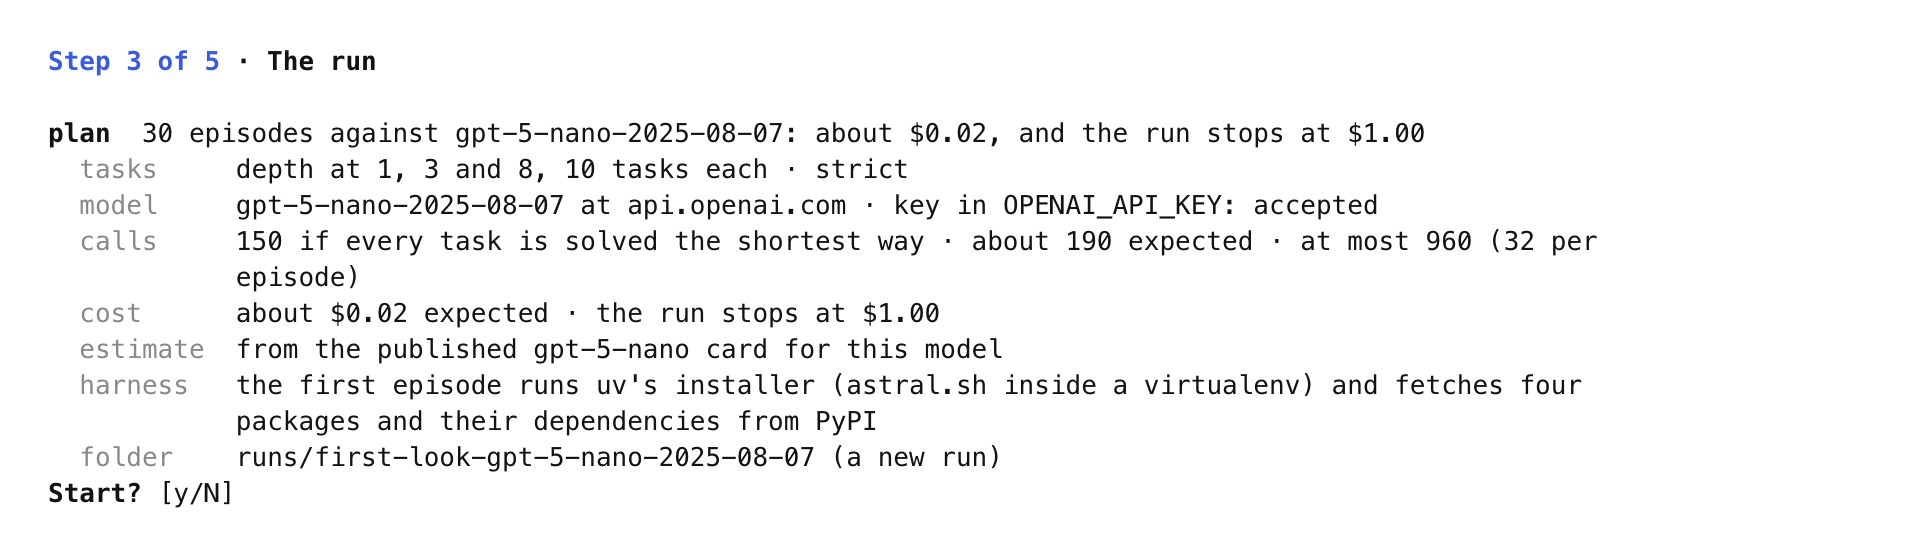
Before anything is spent it checks that the key is accepted and shows its plan: 30 episodes, about $0.02, a stop at $1.00. Then it asks. Answer n and it stops, with nothing called and nothing spent.
As text
Step 3 of 5 · The run

plan  30 episodes against gpt-5-nano-2025-08-07: about $0.02, and the run stops at $1.00
  tasks     depth at 1, 3 and 8, 10 tasks each · strict
  model     gpt-5-nano-2025-08-07 at api.openai.com · key in OPENAI_API_KEY: accepted
  calls     150 if every task is solved the shortest way · about 190 expected · at most 960 (32 per
            episode)
  cost      about $0.02 expected · the run stops at $1.00
  estimate  from the published gpt-5-nano card for this model
  harness   the first episode runs uv's installer (astral.sh inside a virtualenv) and fetches four
            packages and their dependencies from PyPI
  folder    runs/first-look-gpt-5-nano-2025-08-07 (a new run)
Start? [y/N]
In a folder with a run
In a folder that has a run, the session reads the folder and shows where you are: the settings, what each run kept and spent, the latest card’s levels and the next steps. This folder holds one real run, the Petstore API on your own tools with gpt-5-nano.
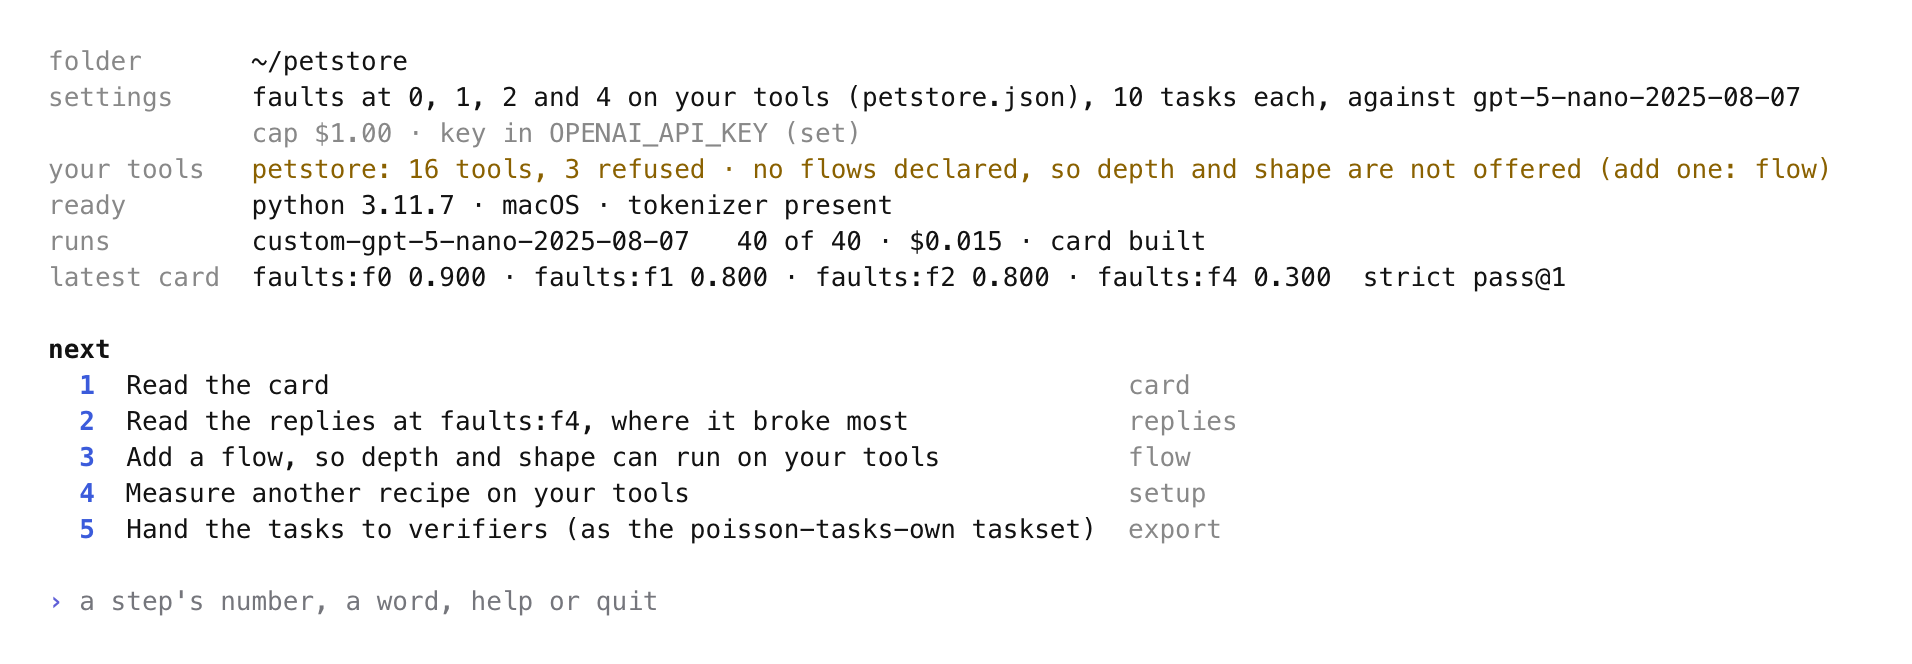
As text
folder       ~/petstore
settings     faults at 0, 1, 2 and 4 on your tools (petstore.json), 10 tasks each, against gpt-5-nano-2025-08-07
             cap $1.00 · key in OPENAI_API_KEY (set)
your tools   petstore: 16 tools, 3 refused · no flows declared, so depth and shape are not offered (add one: flow)
ready        python 3.11.7 · macOS · tokenizer present
runs         custom-gpt-5-nano-2025-08-07   40 of 40 · $0.015 · card built
latest card  faults:f0 0.900 · faults:f1 0.800 · faults:f2 0.800 · faults:f4 0.300  strict pass@1

next
  1  Read the card                                                   card
  2  Read the replies at faults:f4, where it broke most              replies
  3  Add a flow, so depth and shape can run on your tools            flow
  4  Measure another recipe on your tools                            setup
  5  Hand the tasks to verifiers (as the poisson-tasks-own taskset)  export

› a step's number, a word, help or quit
The card
Strict pass@1 at each level with its 95% interval, then what the card means and what it does not claim. It is one run, 10 tasks at each level with one attempt each: an example of what a card shows, not a result about gpt-5-nano.
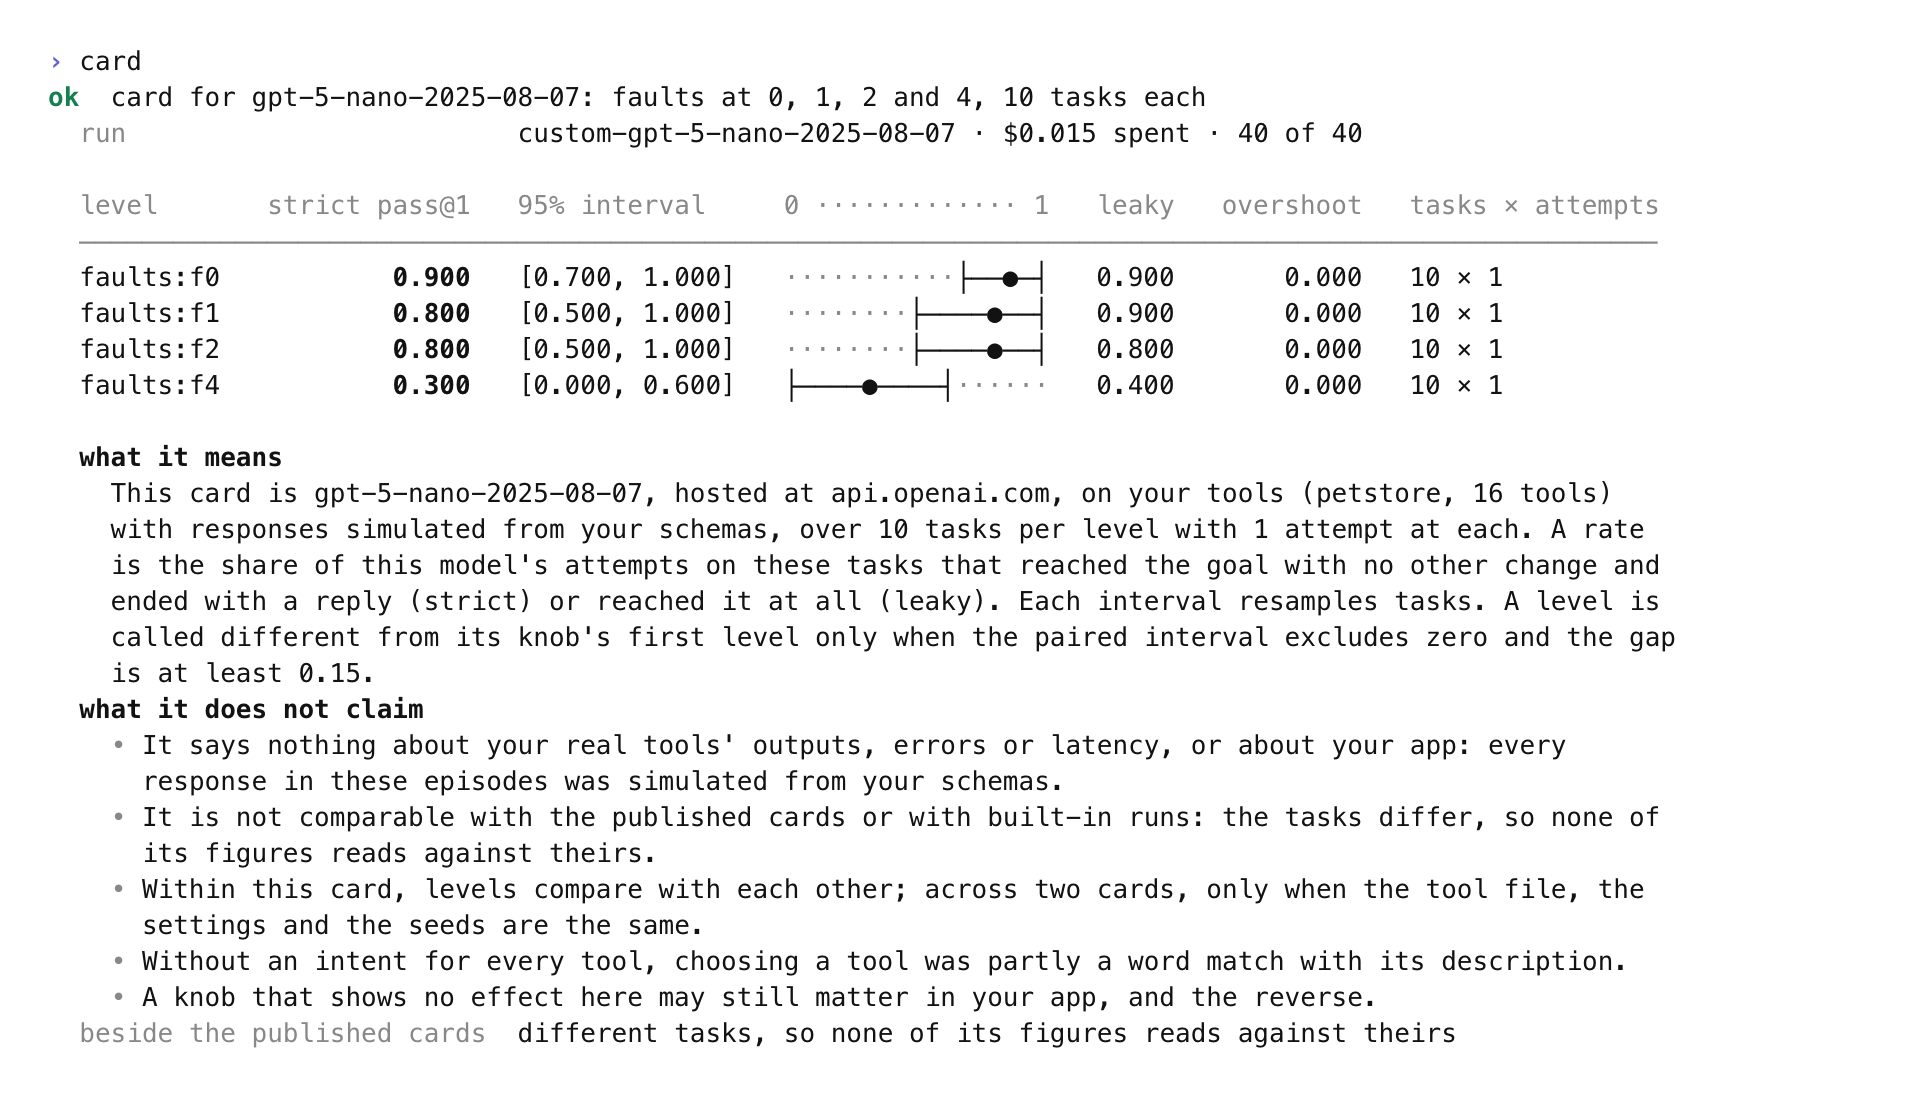
As text
› card
ok  card for gpt-5-nano-2025-08-07: faults at 0, 1, 2 and 4, 10 tasks each
  run                         custom-gpt-5-nano-2025-08-07 · $0.015 spent · 40 of 40

  level       strict pass@1   95% interval     0 ············· 1   leaky   overshoot   tasks × attempts
  ─────────────────────────────────────────────────────────────────────────────────────────────────────
  faults:f0           0.900   [0.700, 1.000]   ···········├──●─┤   0.900       0.000   10 × 1
  faults:f1           0.800   [0.500, 1.000]   ········├────●──┤   0.900       0.000   10 × 1
  faults:f2           0.800   [0.500, 1.000]   ········├────●──┤   0.800       0.000   10 × 1
  faults:f4           0.300   [0.000, 0.600]   ├────●────┤······   0.400       0.000   10 × 1

  what it means
    This card is gpt-5-nano-2025-08-07, hosted at api.openai.com, on your tools (petstore, 16 tools)
    with responses simulated from your schemas, over 10 tasks per level with 1 attempt at each. A rate
    is the share of this model's attempts on these tasks that reached the goal with no other change and
    ended with a reply (strict) or reached it at all (leaky). Each interval resamples tasks. A level is
    called different from its knob's first level only when the paired interval excludes zero and the gap
    is at least 0.15.
  what it does not claim
    • It says nothing about your real tools' outputs, errors or latency, or about your app: every
      response in these episodes was simulated from your schemas.
    • It is not comparable with the published cards or with built-in runs: the tasks differ, so none of
      its figures reads against theirs.
    • Within this card, levels compare with each other; across two cards, only when the tool file, the
      settings and the seeds are the same.
    • Without an intent for every tool, choosing a tool was partly a word match with its description.
    • A knob that shows no effect here may still matter in your app, and the reverse.
  beside the published cards  different tasks, so none of its figures reads against theirs
Real output of a session on a fresh install, drawn by a terminal emulator; the text of each picture is under it. The last two are the same session opened on the folder of one real run, made on 2026-10-21.
Nine dials, and what the evidence says
Four make tasks harder on at least one model. Five don’t yet, and say so.
Depth and the decoy-tools dial are measured on the two published cards. The other seven were measured by a pre-registered probe on the same two models, 60 tasks and 2 attempts per arm, scored on strict pass@1, lowest level against highest. A dial bites when it drops strict pass@1 by at least 0.15, with a 95% interval that excludes zero; for faults, block and arguments the control arm, which adds the same length without the dial, has to drop as well. Every dial works from the command line, whatever its status.
-
Depth
Shown to make tasks harder on gpt-5-nano · the published cards
How many chained calls the goal is away.
depth· levels 1, 2, 3, 5, 8gpt-5-nano
Harder: strict pass@1 0.547 at d1, 0.237 at d3, 0.177 at d5, then 0.870 at d8, where no stage lies past the goal.
Qwen3-8B
Not harder: it reaches the goal at every depth and goes past it at low levels, so strict pass@1 climbs from 0.000 at d1 to 0.997 at d8.
-
Faults
Shown to make tasks harder on Qwen3-8B · the probe
How many calls on the way answer "unavailable" and must be made again.
faults· levels 0, 1, 2, 4gpt-5-nano
Does not bite: 0.975 at
faults:f0, 0.575 atfaults:f4. Against the control arm, which adds the same length without the dial, the drop is 0.142, under 0.15.Qwen3-8B
Bites: 0.992 at
faults:f0, 0.167 atfaults:f4. -
History
Shown to make tasks harder on both models · the probe
How many tokens of earlier tool work the conversation holds.
history· levels 0, 300, 600, 1200, 2400gpt-5-nano
Bites: 0.908 at
history:t0, 0.225 athistory:t2400.Qwen3-8B
Bites: 1.000 at
history:t0, 0.692 athistory:t2400. -
Shape
Shown to make tasks harder on Qwen3-8B · the probe
How many records four stage calls advance side by side.
shape· levels 1, 2, 4gpt-5-nano
Does not bite: 0.325 at
shape:w1, 0.625 atshape:w4.Qwen3-8B
Bites: 0.967 at
shape:w1, 0.608 atshape:w4. -
Decoy tools
Experimental · the published cards
How many of the sixteen tools in the block are decoys.
distractor· levels 0, 2, 4, 8, 14gpt-5-nano
Not harder: strict pass@1 stays between 0.90 and 0.96, and no two adjacent levels differ.
Qwen3-8B
Not harder: strict pass@1 is 0.98 or more at every level.
-
Similarity
Available · retested in v2
How many digits of the right tool's ledger number each lookalike tool shares.
similarity· levels 0, 1, 2, 3gpt-5-nano
Does not bite: 0.408 at
similarity:s0, 0.458 atsimilarity:s3.Qwen3-8B
Does not bite: 1.000 at
similarity:s0, 1.000 atsimilarity:s3. -
Block
Available · retested in v2
How many tools are offered.
block· levels 8, 16, 32, 64gpt-5-nano
Does not bite: 0.883 at
block:k8, 0.950 atblock:k64.Qwen3-8B
Does not bite: 1.000 at
block:k8, 1.000 atblock:k64. -
Arguments
Available · retested in v2
How many values each call must carry, copied from the request.
arguments· levels 2, 4, 6, 8gpt-5-nano
Does not bite: 0.808 at
arguments:a2, 0.717 atarguments:a8.Qwen3-8B
Does not bite: 0.983 at
arguments:a2, 0.833 atarguments:a8. Against the control arm, which adds the same length without the dial, the drop is 0.100, under 0.15. -
Spread
Available · retested in v2
How many tool answers the entry code is split across.
spread· levels 1, 2, 4gpt-5-nano
Top easier: 0.067 at
spread:p1, 0.317 atspread:p4. The top level passed more often than the base.Qwen3-8B
Cannot tell: 0.008 at
spread:p1, 0.000 atspread:p4. The base task passed 0.008, too seldom for a drop to show.
Strict pass@1 at the dial’s lowest and highest level. Two small models, measured once, are not the last word: the four marked “Available · retested in v2” are measured again on current models in the next release, and every contrast with its interval is in knobs and arms.
On your own tools
Every dial but the decoy-tools dial is offered, as far as your tools can support it. Depth and shape need flows. A flow is a link you declare between two of your tools: which field of one tool’s answer goes into which argument of the next. Tasks never guesses one, so without flows, depth and shape are listed as unavailable.
poisson-tasks init --own-flow FROM.FIELD:TO.PARAMWhat a first run costs, and what it leaves
A first run is 30 episodes against gpt-5-nano: about two cents.
Before it spends anything, the run shows its plan, the expected cost and the cap, and it stops at the cap. By default the cap is the larger of $1.00 and twice the estimate, rounded up to a whole dollar. Ctrl-C stops a run, and running it again picks up where it stopped.
It writes to the folder you work in (tasks.toml, runs/,
tasks/), and outside it only these:
- the tokenizer file, 3.6 MB, fetched once into the installed package;
- the harness’s setup:
uvanduvxin~/.local/bin, their receipt in~/.config/uv, and four packages in uv’s cache; - verifiers’ cache, in
~/.cache/verifiers; - one
/tmp/vf-port-<hex>file per episode, and one empty uv lock file in the temporary folder.
Your key goes to your model’s endpoint and nowhere else. The docs list each of these in full.
How the probe ran
Three things about the run, disclosed wherever its results appear.
- A check changed after its first result (gpt-5-nano). As registered, phase 1 stopped the probe if any of 21 base episodes made no tool call. gpt-5-nano’s first phase 1 stopped on 1 of 21, where the model asked for a record id in plain text instead of calling a tool. On 2026-10-13 the check was changed to the published cards’ own rule (stop above 10%, so 3 or more of 21), and the recorded phase 1 was read again once with nothing rerun. It passed. Qwen3-8B passed under the original rule.
- A crash at the start, and one arm run again (gpt-5-nano). The run hit macOS’s
open-file limit while its first arm,
similarity:s0, was in flight. The episodes lost in the crash voided that arm, so it was run once more, as the pre-registration allows for a cause on our side. The void attempt is kept. gpt-5-nano cost $1.60 of a $4.00 cap. The crash is fixed in this release: a run raises the limit itself, or refuses in one line saying how. - More time for Qwen3-8B. The Colab run reached its two-hour allowance with 14 of 18 arms done and stopped cleanly. It was given more time and finished the last four with the same settings, using 2.56 hours in all.
The published cards
A card says what each level is worth to one named model.
60 tasks per level, 5 attempts each. Each level shows its pass rate with an interval, how often the model went past the goal, and its cost in calls and tokens. Both cards ship inside the package and rebuild byte for byte from their records.
What it cannot tell you yet
A level’s number is one model’s.
The two cards agree on none of the 12 adjacent level pairs and disagree on one, depth 2 against 3, in opposite directions. No number is claimed for a model that has not been run, and a dial that did not bite on these two models may bite on another.
The published cards were measured before the newer dials existed, so a card from your own
run can’t be read beside them in this release: the comparison refuses in one line, and it
comes back with v2’s cards. OpenAI shuts down the gpt-5-nano-2025-08-07 snapshot on
2026-12-11, and v2’s cards run on current models, a Claude model among them.
verify doesn’t judge tasks made on your own tools yet; a run’s card judges
each of those episodes by replay. Windows isn’t supported.
The release
0.4.2, released on 2026-11-12.
What it changed is in its
changelog entry, and the notes of every release
are in the docs changelog. The docs are copied from the repository
at c8d48af.