Poisson Tasks is out. Find where your agent breaks before your users do. Read the launch
Poisson Prove is out. It tells you whether a change to your agent really changed how often it fails. Read the launch
Poisson Labs

Poisson LabsAI agents

Catch prompt, model and tool-handling regressions before your users do.

Rerun the same agent and the score moves a point with nothing changed. Poisson measures that noise, then compares before and after on the same seeds, in CI, so you know whether a fix actually held.

τ²-bench airline · the same agent, twice

45.0% → 44.0%of tasks solved, run one then run two

44 pairs came out differently156 agreed

Identical configuration and seed, temperature zero. No significant change in the score. Read the study

01Why a score isn't enough

Identical, then not.

One customer-service task, both runs, token for token the same for 4 calls. At the next, one hands the customer to a person and passes; the other cancels the reservation and fails.

one task, both runs, call by call

τ²-bench airline task 28 seed 1207528101 temperature 0 gpt-4.1-mini

Both runs, identical

  1. 0 user message · 27 tokens
  2. 1 agent message · 46 tokens
  3. 2 user message · 38 tokens
  4. 3 agent get_reservation_details

Call 4: the runs part. The agent is given the same 3,659 tokens in both runs. It writes 96 tokens in one and 129 in the other.

Run R 20260915T210140Z-4847

  1. 4 agent message · 96 tokens
  2. 5 user message · 59 tokens
  3. 6 agent transfer_to_human_agents
  4. 7 agent message · 18 tokens
  5. 8 user message · 3 tokens

Passed solved · COMMUNICATE 1 · DB 1

Run R′ 20260915T211148Z-965d

  1. 4 agent message · 129 tokens
  2. 5 user message · 62 tokens
  3. 6 agent cancel_reservation
  4. 7 agent message · 111 tokens
  5. 8 user message · 95 tokens
  6. 9 agent transfer_to_human_agents
  7. 10 agent message · 18 tokens
  8. 11 user message · 3 tokens

Failed unsolved · COMMUNICATE 1 · DB 0

02How it works

From your tool schema to a check on the pull request.

TasksAvailable

Build the conditions.

It reads your OpenAI tools file, MCP tool list or OpenAPI document and generates seeded tasks. Nothing calls a model until you say yes to the cost.
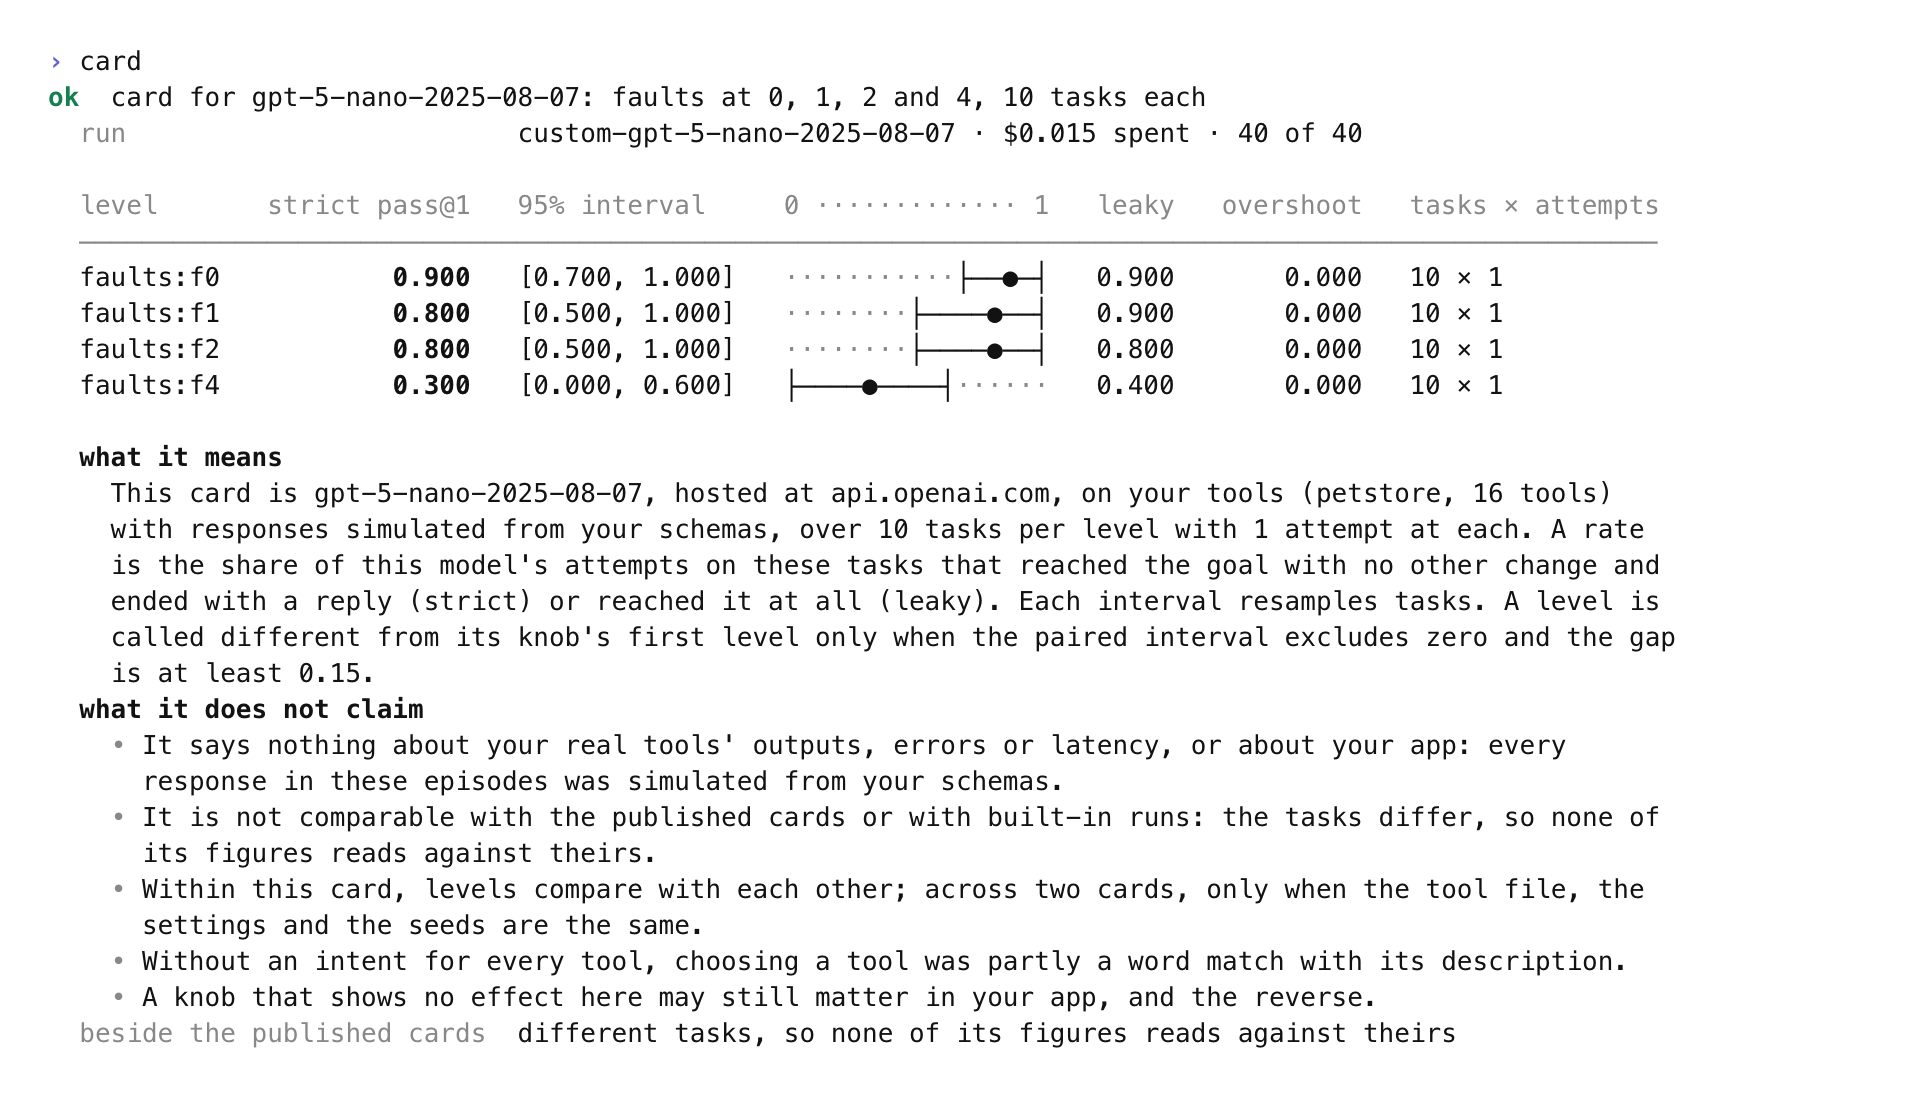
poisson-tasks · the Petstore API · gpt-5-nano
A Tasks card: strict pass at one, at faults 0, 1, 2 and 4, with 95% intervals.
One run on simulated replies: 10 tasks a level, 40 episodes, $0.015. An example, not a result about the model.

TracePrivate wheel

Locate the step that broke.

It reads the runs you already have, from DeepEval and Ragas today, and says which step they die at.

poisson-trace compare · a planted change
review q = 1.67e-20 A · 206 B · 422 sample q = 0.865 A · 180 B · 157 measure q = 0.422 A · 146 B · 114 RUNS THAT DIED AT THIS STEP, OF 2,000 PER ARM
A, the baseline B, one stage's failure rate doubled significantly more deaths in B, q < 0.05
One stage's failure rate was doubled and sealed before any run. Trace called the pair different (p = 1.7e-9) and named review, the stage the seal named. Read the study

ProveAvailable

Get a verdict per condition.

Before and after, on the same seeds. It says which conditions moved, which were too small to tell, and what the run could not have caught.
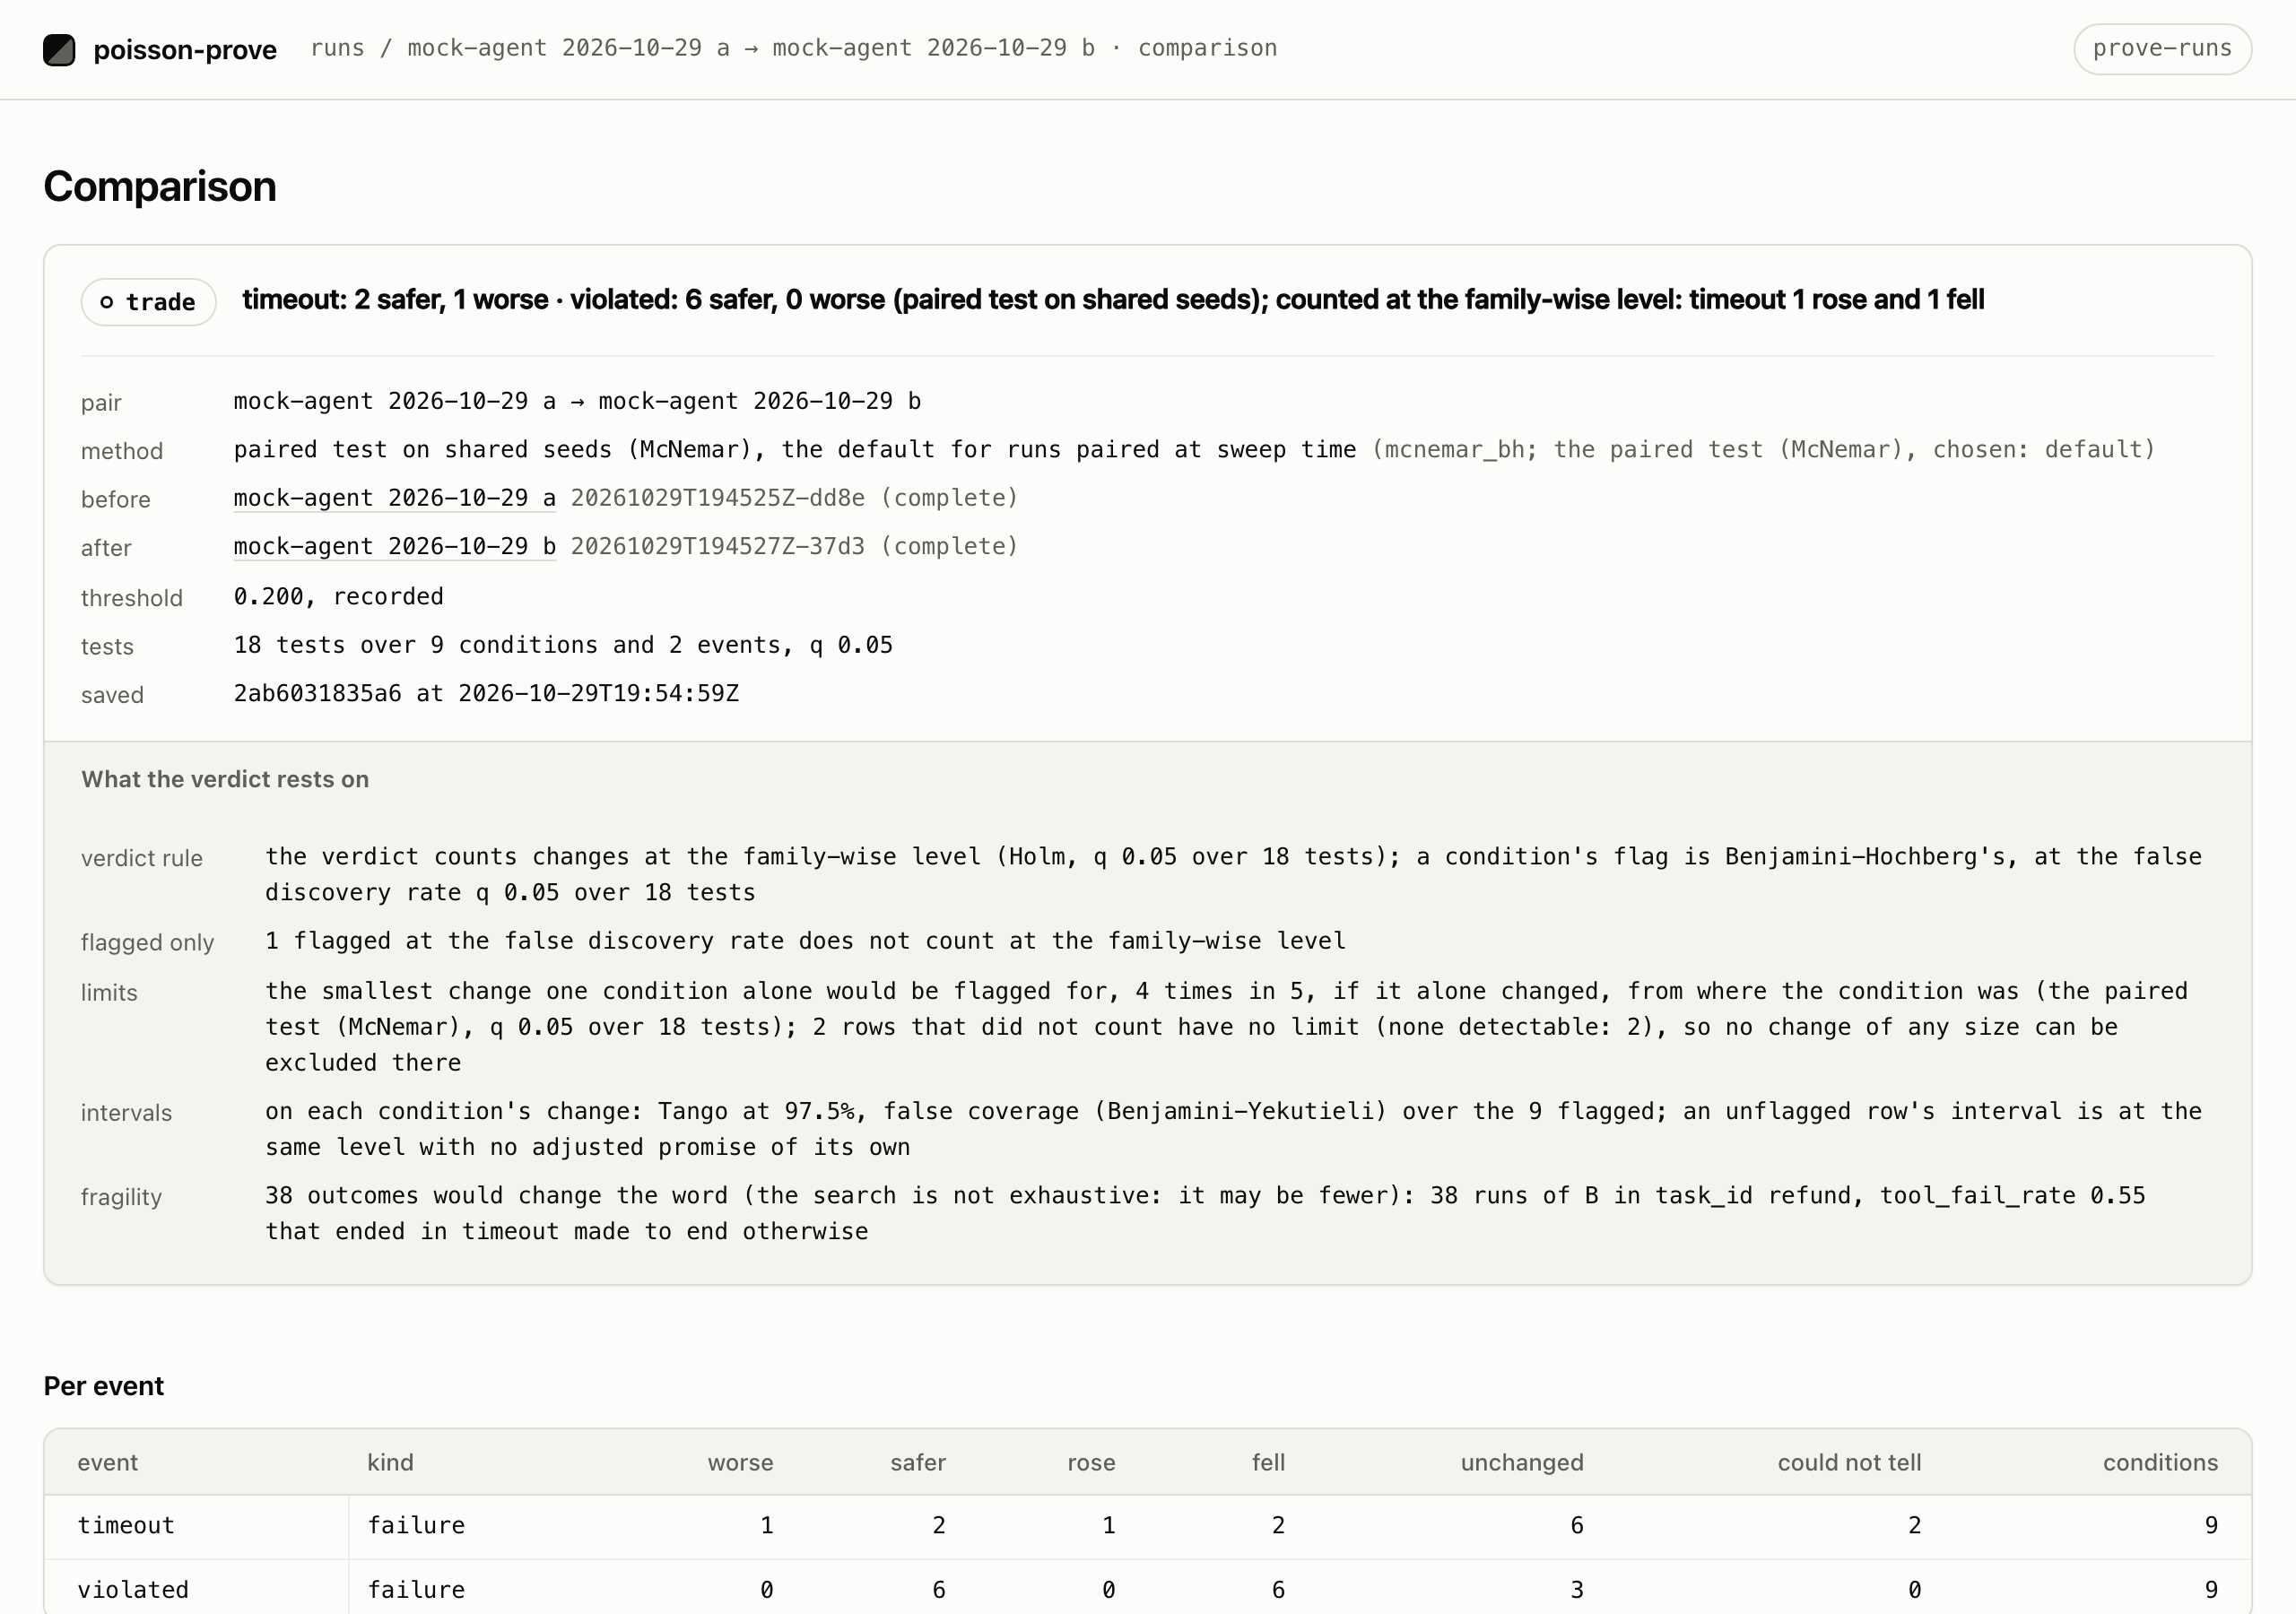
poisson-prove · the comparison page
The dashboard's comparison page: the verdict trade with its sentence, the method, the runs, what the verdict rests on, and a count per event
From the packaged example, on a mock agent: the page is real and its counts measure nothing.

ProveAvailable

Fail the pull request.

A condition fails the check only when it is significantly worse than its own baseline, corrected for testing every condition at once.

.github/workflows/agent.yml
- name: Check the agent  run: |    poisson-prove sweep agent.toml \        --target my_agent:rollout \        --pair-with <main-run> --yes    poisson-prove check <main-run> <this-run> \        --event violated --fail-on worse

03Integrations

Bring the stack you already run.

Your test runners and tracers

  • DeepEval
  • Ragas
  • promptfoo
  • Inspect
  • OpenAI Evals
  • Braintrust
  • Weave
  • +5 more

Your agent

  • OpenAI Agents SDK
  • LangGraph
  • CrewAI

Your cloud

  • AWS
  • GCP
  • Azure
  • Your machine
  • Modal

Poisson

  1. Break hunts for the conditions that make your agent fail, with Monte pointing it where failure is likely.
  2. Trace reads the runs you already have, step by step.
  3. Prove reruns every condition before and after a change, on the same seeds, with a test per condition corrected for testing them all at once.

What you get

A verdict per condition

  • Improved
  • Regressed
  • Too small to tell, with the limit

In CI, the check fails on a regression.

MATH ASINFRASTRUCTURE.

Get started Talk to us